What fine-tuning actually changes
Fine-tuning is the one technique on this page that touches a model's weights. Prompting, retrieval and caching all leave the weights exactly as they were and change what the model sees or how fast it answers. Fine-tuning is different: you train further on top of a base model, and the resulting weights are what you're now serving. That's the entire reason it's expensive to get wrong. You're not adjusting an input, you're changing the thing itself.
Which is exactly why it should be the last thing you reach for, not the first.
The ladder, and the three reasons to climb it
Step 1 of 4
1. Prompt
Try steering the base model with a better prompt first. Most tone and format problems live here, and it costs nothing to test.
2. RAG
If the model doesn't know something, retrieval fixes that without touching the weights. Knowledge changes daily; fine-tuning doesn't refresh itself.
3. Caching
If the model is slow or expensive per call, prompt caching or a smaller model usually fixes that, not a training job.
4. Fine-tune, last resort
Only past whichever step actually stops solving the problem, and only for one of three reasons: a rigid structured output, cost/latency distillation, or a narrow domain tone a prompt only approximates.
Bedrock's fork: one API, four jobs
Bedrock's CreateModelCustomizationJob API asks which of four jobs you actually want, via its customizationType parameter. Match the reason to the job, not the other way around.
Supervised, on your own labelled input/output pairs. The classic case: you have examples of exactly what the model should output for a given input, and you train on them directly. Best fit for a rigid structured output a prompt can't hold consistently at scale.
Unlabelled domain data, for building broader domain adaptation rather than a specific task. No input/output pairs needed, just a corpus of text in the register or domain you want the model to absorb. Best fit for a narrow domain vocabulary or tone.
No training pairs at all. Point Bedrock at a stronger "teacher" model and a weaker "student" model, and it generates the synthetic training set from the teacher's own responses. GA May 2025; AWS's own figures put distilled models at up to 500% faster and 75% cheaper than the teacher, under 2% accuracy loss on retrieval-style tasks. The most direct route to cost or latency distillation, since you skip building a labelled dataset entirely.
Nova-only today. You supply a reward function instead of a fixed answer key, and the job trains against that signal. "Did the tool call parse" is exactly the kind of thing you can grade programmatically, which makes this the most direct fit for structured output and tool-calling reliability specifically.
Serving it forks again, into three different bills
Bedrock's own documentation is plain: "if you customized a model, you must purchase Provisioned Throughput to be able to use it." That's true, but it's not the whole story any more.
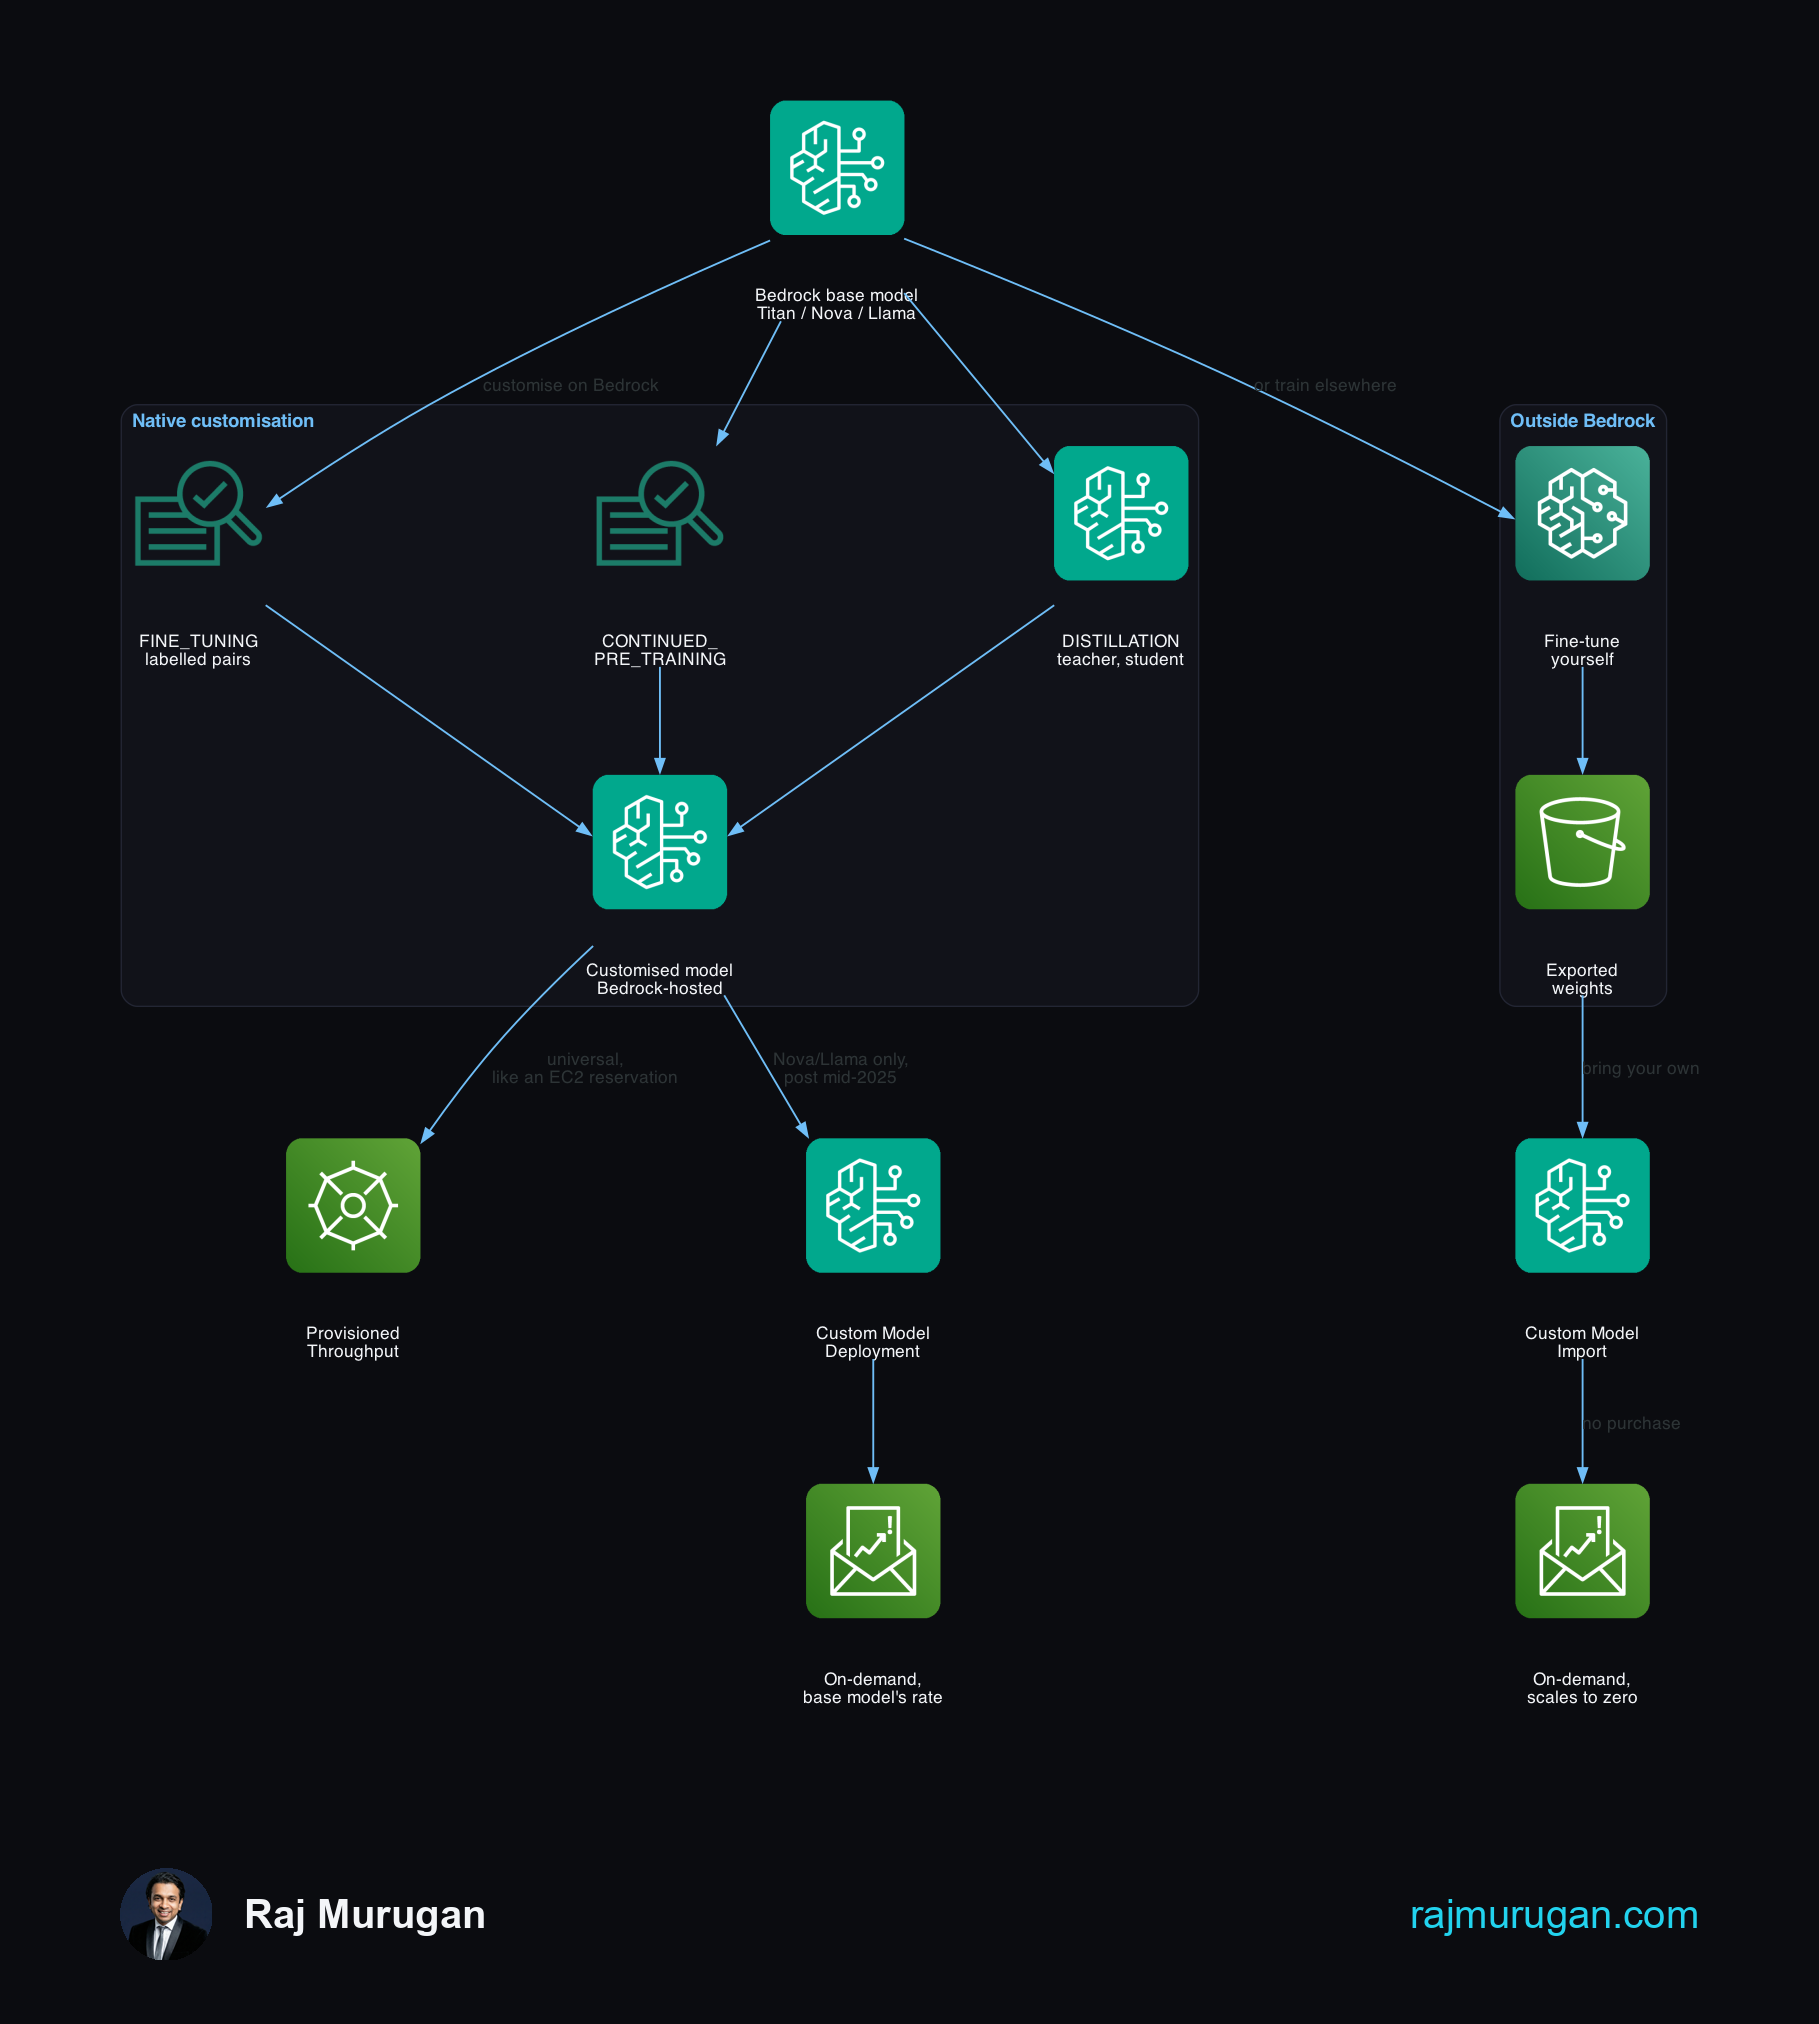
The universal default. Reserved capacity, billed hourly, whether a request arrives or not. Priced today, Amazon Nova Micro and Nova Pro cost the same $60.50/hr per model unit with no commitment, despite Micro costing a fraction of Pro on demand, because you're renting a model unit, not a token budget. Works for any customised model, any region Bedrock customisation supports.
A narrower on-demand exception, live since 16 July 2025. Specific Nova models (Lite, 2 Lite, Micro, Pro, all us-east-1) and Meta Llama 3.3 70B Instruct (us-west-2), priced at the base model's own token rate, but only if the underlying model was customised on or after that date (15 September 2025 for Llama). Everything else, every Titan customisation, every model customised before those dates, still has exactly one way to serve it.
Skips CreateModelCustomizationJob entirely: for weights you trained yourself outside Bedrock. Billed per Custom Model Unit-minute, currently $0.05718 in us-east-1, scaling to zero five minutes after the last invocation. The trade-off is a real cold start, seconds to a couple of minutes, on the first request back.
Full write-up
The complete pricing table, the worked cost maths (steady 24/7 traffic vs a genuinely bursty workload), and where the sourcing came from: You probably don't need to fine-tune.